MoE (mixture of experts)
Türkçe: MoE (uzman karışımı)
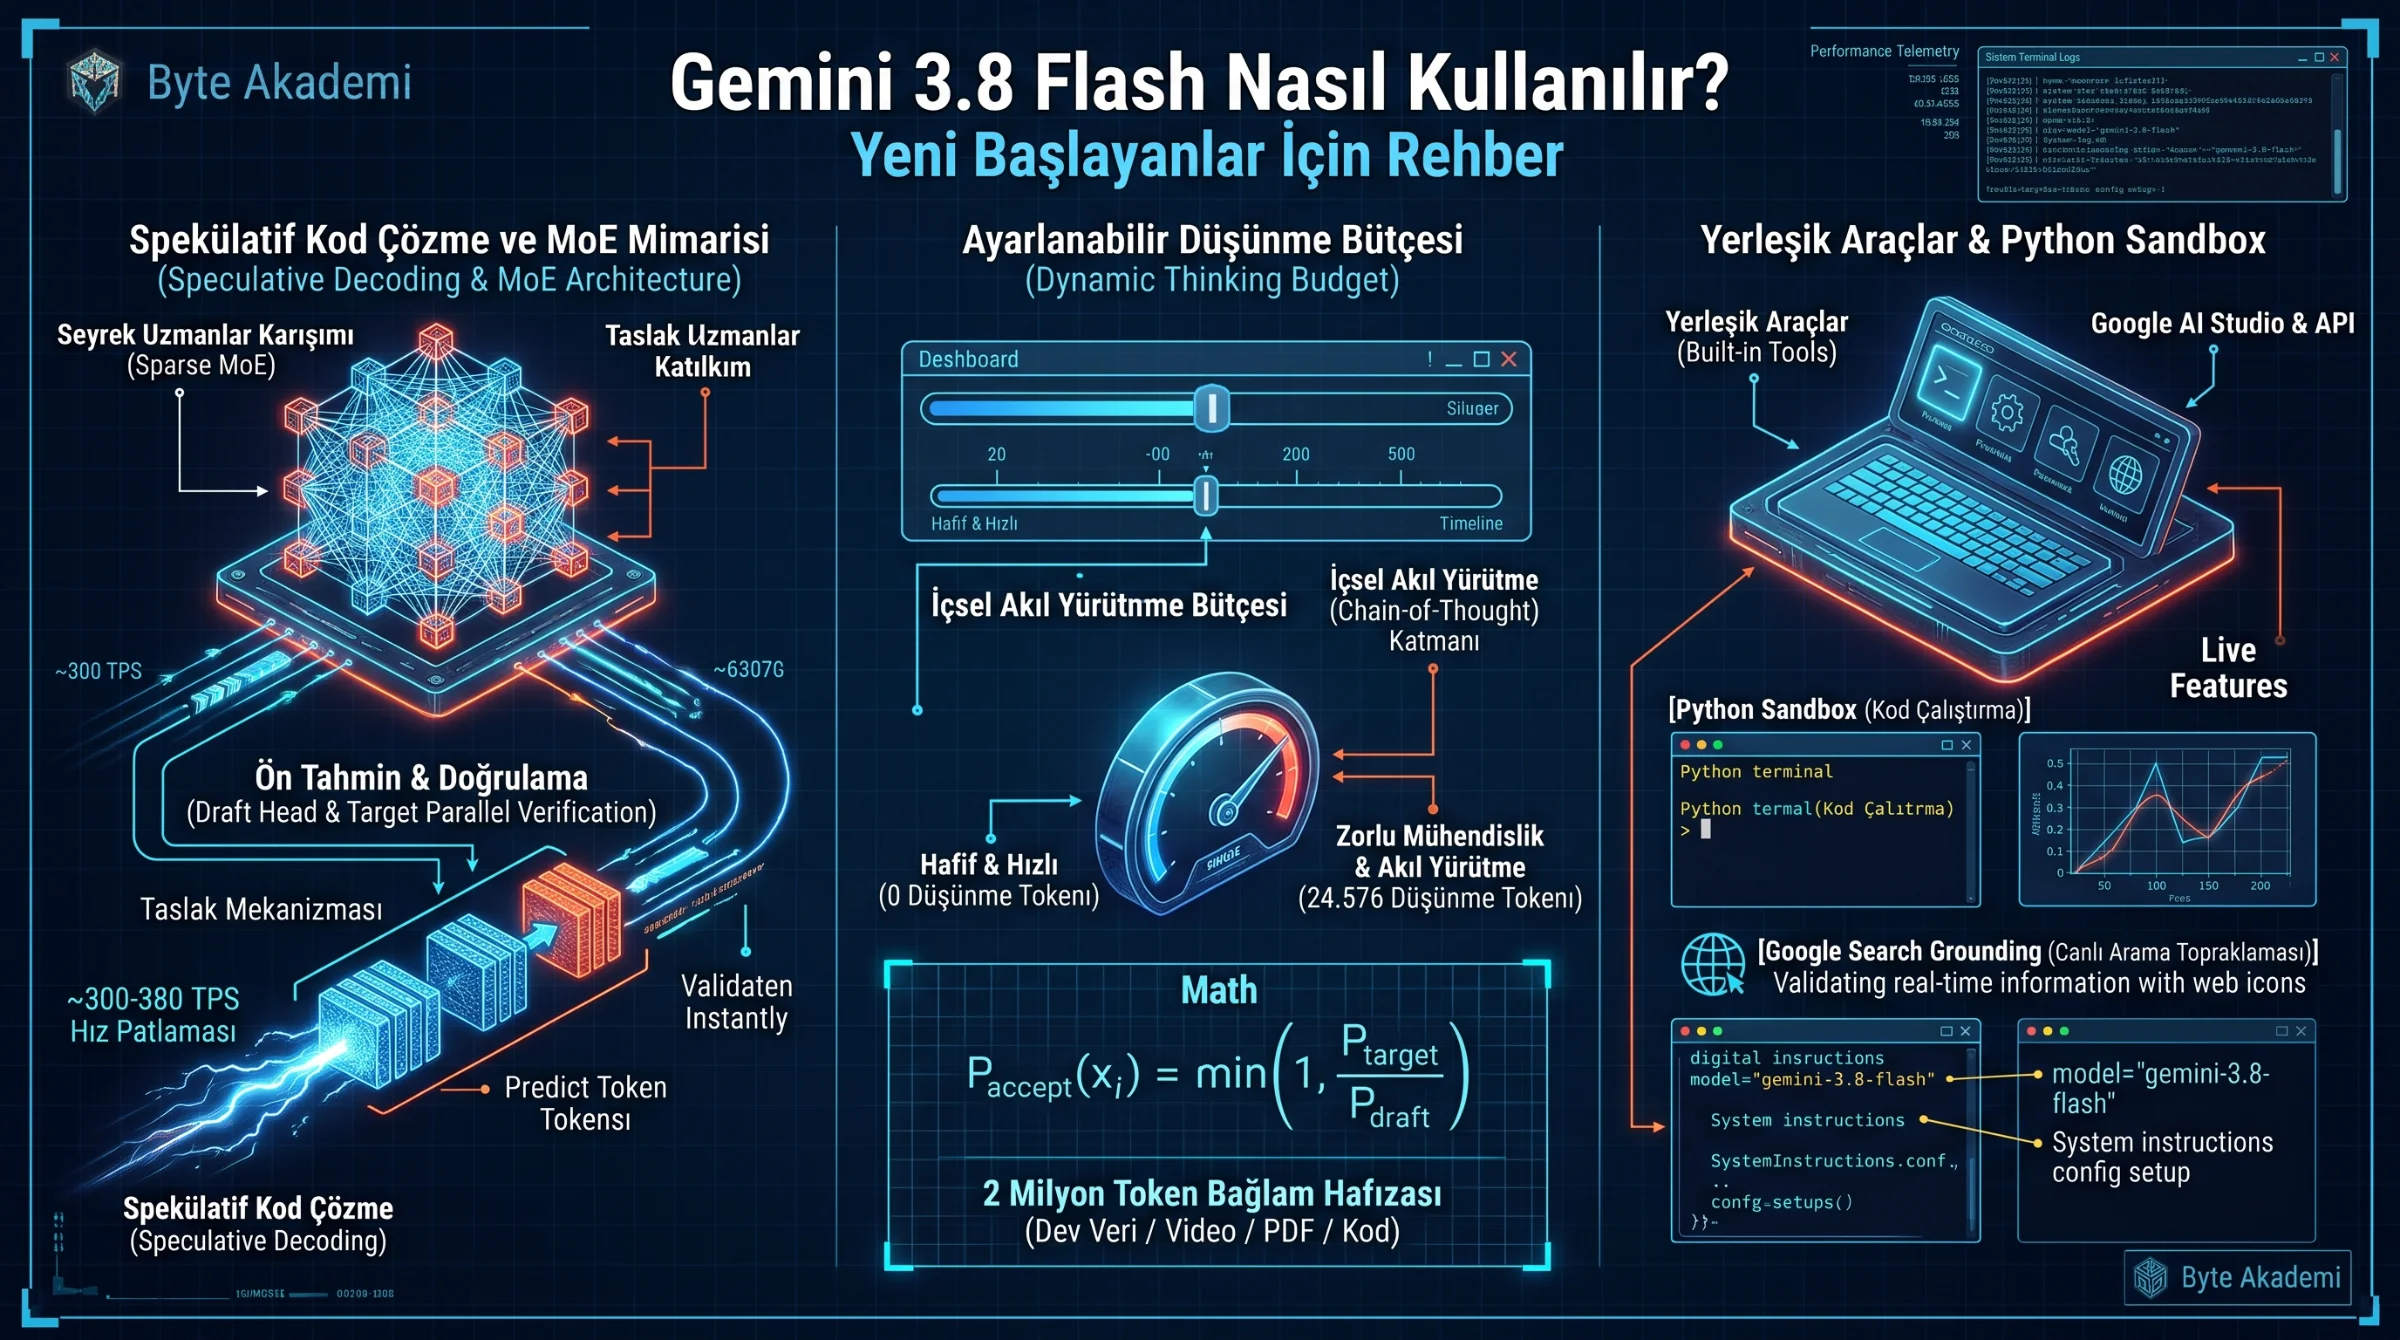
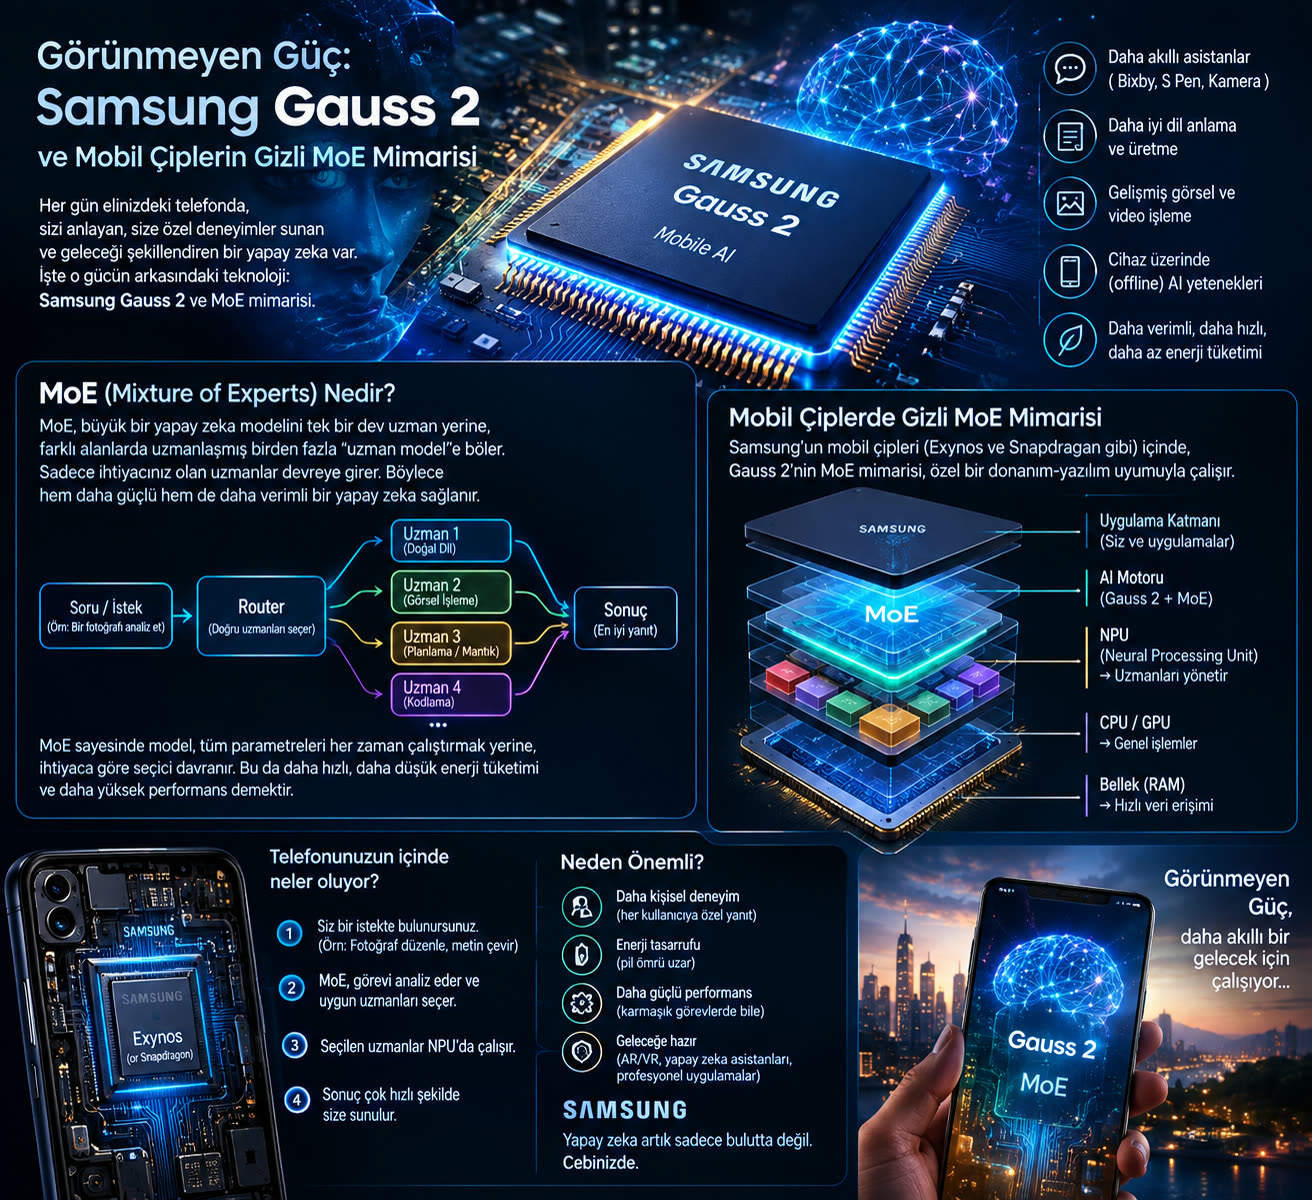
An architecture in which the model consists of many "expert" sub-networks and only a few of them run for each token.
// EXPLANATION
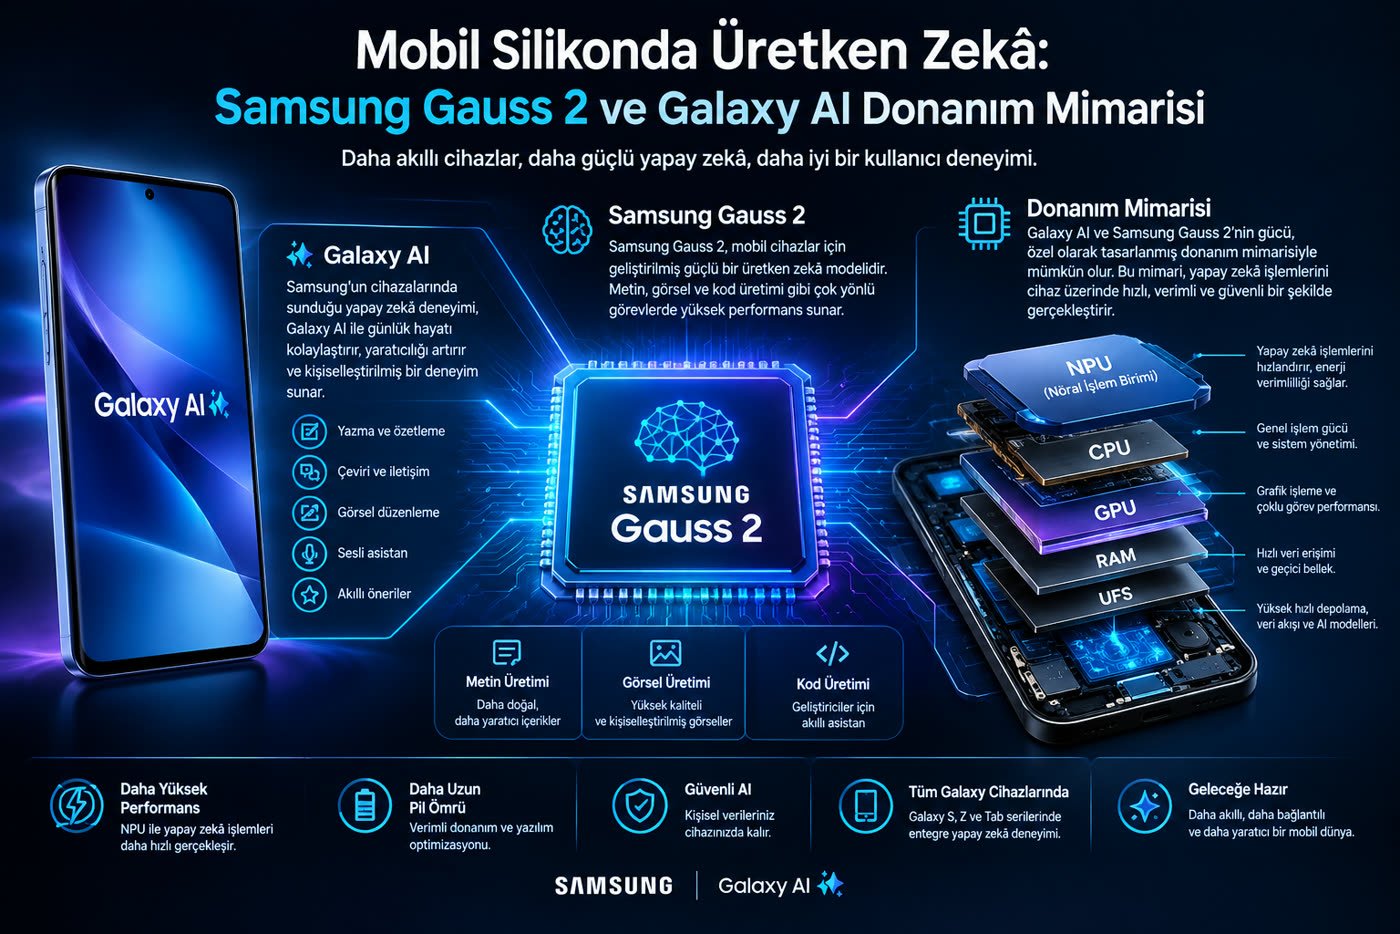
Even if the total parameter count is huge, only the selected experts are computed each step, which lowers compute cost. It is seen as one way to run large models on energy-limited devices such as phones.
// ALSO KNOWN AS
MoEmixture of expertsmixture-of-experts
// RELATED TERMS
Transformer architectureThe neural-network architecture introduced in 2017 that computes relationships between all words in a text in parallel using an attention mechanism.
LLM (large language model)A neural network trained on very large amounts of text that generates text by probabilistically predicting the next piece (token) of a sequence.
NPU (neural processing unit)A dedicated processing unit designed to accelerate neural-network computation (matrix/tensor operations) at very low energy.