Inference
Türkçe: Çıkarım (inference)
The stage in which a trained model produces output for new input; the phase that serves users after training.
// EXPLANATION
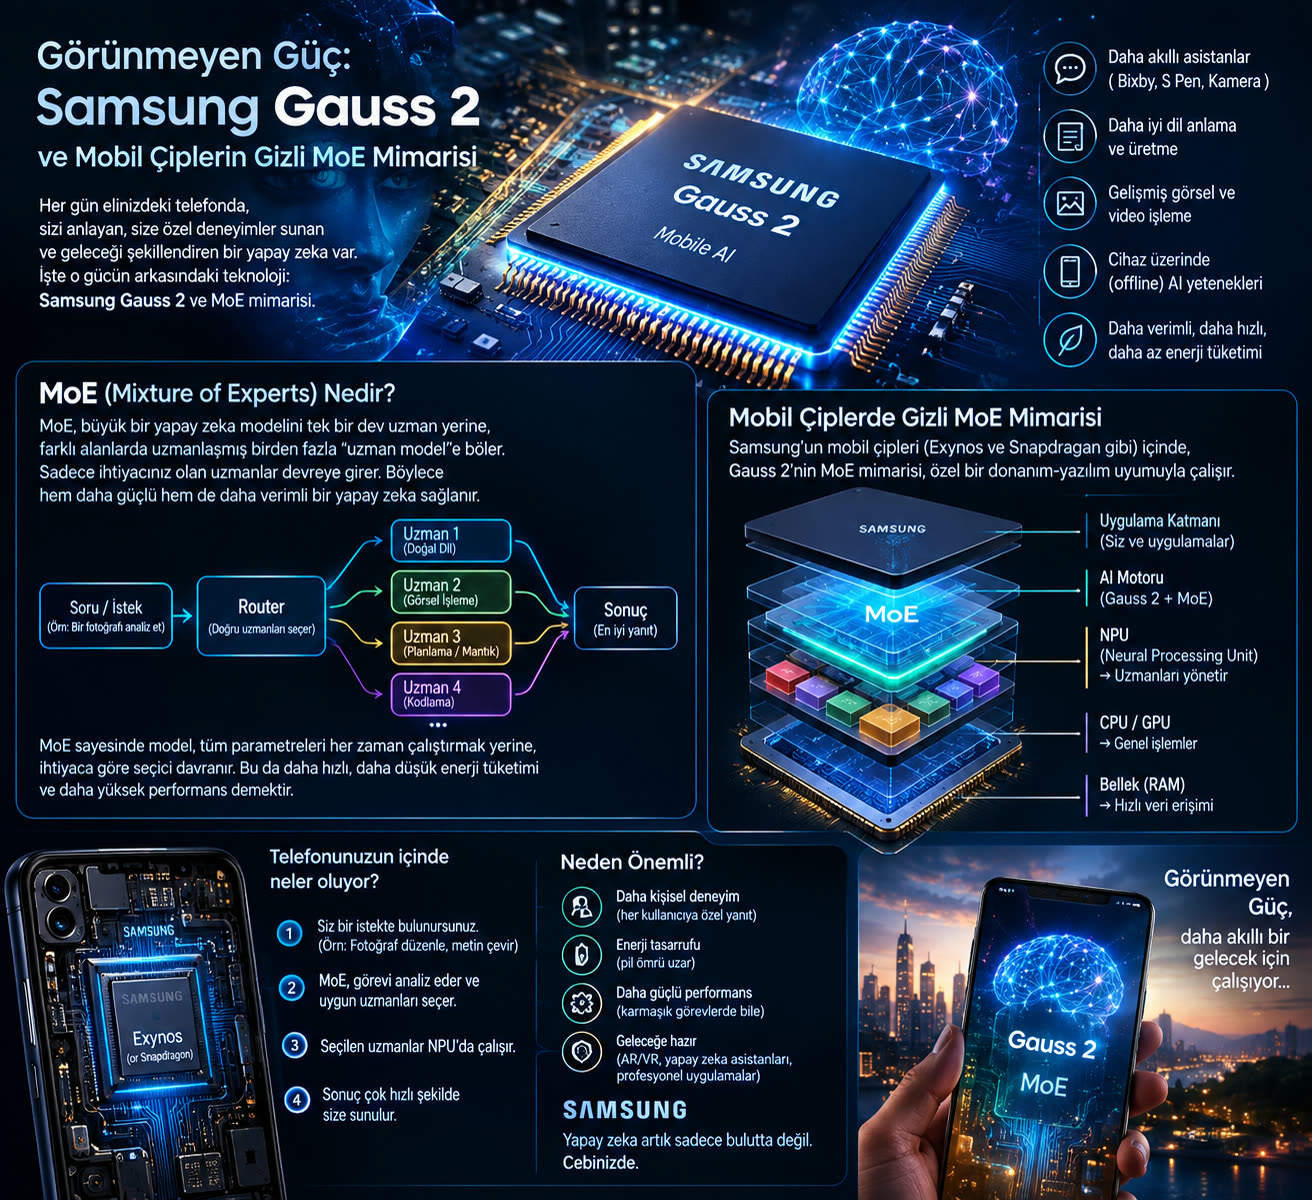
Training is very expensive and one-off, while inference runs continuously. Inference speed depends on memory bandwidth, model precision and hardware (GPU/NPU); running locally means doing this phase on your own device.
// ALSO KNOWN AS
inference
// RELATED TERMS
LLM (large language model)A neural network trained on very large amounts of text that generates text by probabilistically predicting the next piece (token) of a sequence.
VRAMThe high-bandwidth memory on the graphics card itself; an AI model's weights have to fit into it.
QuantizationA technique that lowers memory and speed cost by storing model weights with fewer bits (for example 8 or 4 instead of 16).
NPU (neural processing unit)A dedicated processing unit designed to accelerate neural-network computation (matrix/tensor operations) at very low energy.